Vision-language-action guide
VLA robotics: models, code and tactile feedback
How do vision-language-action models work? Compare VLA architectures, action chunks, open models, deployment tradeoffs and tactile feedback with source links.
Published | Updated by RoboSkin.ai Editorial Team
- 11
- sections
- 9
- questions
- 15
- next routes
Start here
What is VLA in robotics?
VLA stands for vision-language-action. A VLA model takes a robot's visual observations and a language instruction and produces or conditions actions. The robot executes those actions and observes the result, closing the feedback loop.
01 / Observe
Camera images and an instruction describe the scene and task. Some systems also use robot state or touch.
02 / Predict an action
The policy produces action tokens, continuous commands or action chunks, depending on the model.
03 / Execute and observe again
A robot controller executes the action. New observations let the system select or refine the next action.
Model and code starting points
Choose by the work you want to do. These three examples cover a general VLA baseline and two tactile approaches; they are not a performance ranking. Linked project pages and repository release statements checked September 15, 2026. Checkpoints were not downloaded or run. Detailed evidence retains its own review dates below.
Explore an open VLA baseline
OpenVLA 7B
OpenVLA maps images and instructions to robot actions. Its official project links model checkpoints and a training codebase; adapting it still requires a compatible robot interface and task data.
Project with code and model links
Study tactile understanding and prediction
UniTacVLA
UniTacVLA connects tactile reasoning and prediction with action correction. The linked repository currently contains a project-page placeholder, so it is a research reference with no runnable release there.
Repository placeholder
Explore tactile planning and action refinement
VLA-Touch
VLA-Touch adds tactile feedback to planning and a controller that refines VLA actions. Its README links code, data and controller checkpoints, but still lists the modified RDT inference script as coming soon.
Partial implementation and resource links
Comparing broader model families? See the Robot AI Model Directory. For training data, use the robotics dataset comparison.
Research reading room / October 2026
VLA papers: architecture, efficiency and scaling
Read these selected papers alongside the model index to understand action representations, deployment trade-offs and the limits of reported evaluations.
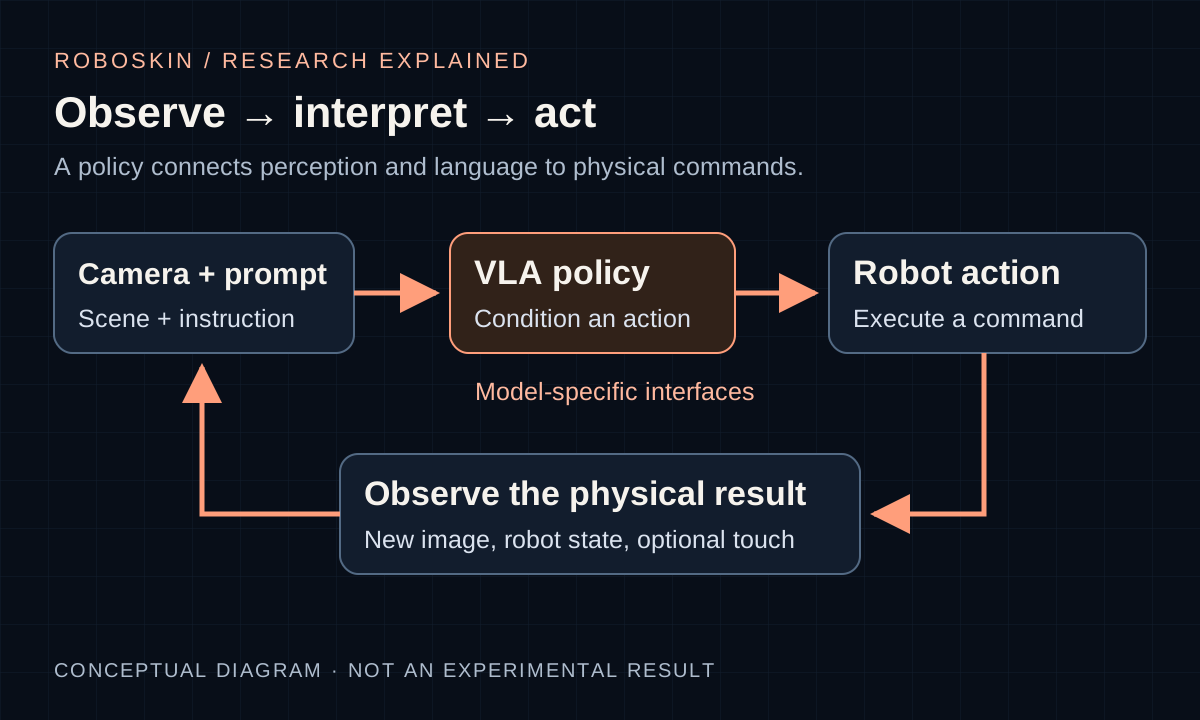
From an instruction to a robot action
A conceptual VLA loop: observations and an instruction condition actions, then fresh observations close the loop. Robot state and touch are optional, model-specific inputs.
Original RoboSkin schematic · explanatory, not experimental data
View full-size diagram ↗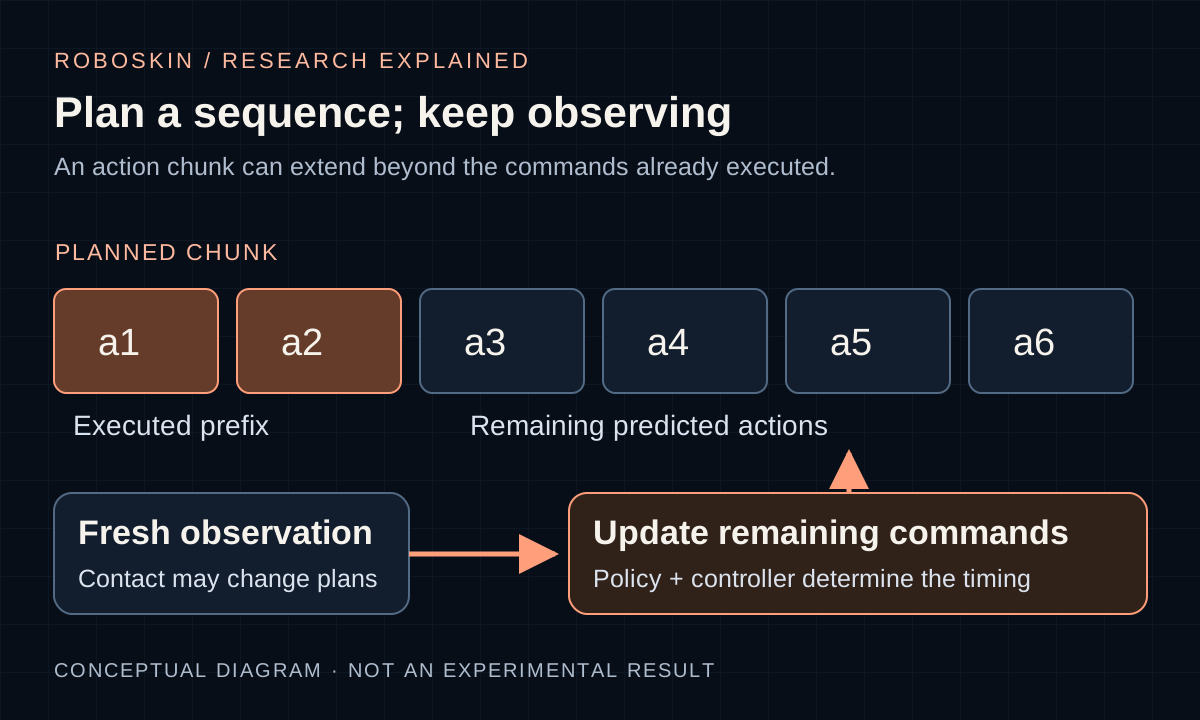
Why action chunks need fresh feedback
An action chunk is a sequence of commands. Executing a shorter prefix and updating the remainder can incorporate new observations; the usable timing depends on the policy and controller.
Original RoboSkin schematic · explanatory, not experimental data
View full-size diagram ↗Sources checked . Selected reading, not an exhaustive ranking. Descriptions summarize the authors' sources; RoboSkin has not reproduced these experiments. Dates below are first publication dates, not dates inferred from a paper identifier.
arXiv preprint
First published
Vela
Vela: Scaling Vision-Language-Action Models with Adaptive Action Curve Parametrization
Vela represents a robot's future actions as a continuous trajectory instead of a fixed-rate action chunk. A compact spline representation lets the same output budget describe either longer smooth motions or shorter motions that need finer control.
Read it for
Read this paper to understand adaptive action horizons, continuous action representations, and the trade-off between long-horizon robot manipulation and contact precision. It changes the action interface while retaining a pi0.5-style model architecture.
Evidence boundary: The physical study covers two task families, while the number of spline control points remains fixed and broader model scaling is left for future work. RoboSkin has not reproduced these experiments.
Method, evaluation and access
- Method
- A flow-matching action expert jointly predicts cubic B-spline control points and a motion-dependent temporal horizon. The authors pretrain in trajectory space on approximately 40,000 hours of public and private robot data, using a shared action interface across embodiments.
- Evaluation context
- The authors evaluate LIBERO-X and EBench simulations, plus egg-cake cooking and potato shredding on a wheeled dual-arm robot. Physical-robot results average success across four subtasks with 10 trials per subtask; these are not whole-task completion rates.
- Artifacts and access
- The paper and demonstration page are public. The official project page still labels code as 'Coming soon' on 9 October 2026.
arXiv preprint; revised 22 July 2026
First published
Xiaomi-Robotics-1
Xiaomi-Robotics-1: Scaling Vision-Language-Action Models with over 100K Hours of Real-World Trajectories
Xiaomi-Robotics-1 studies how VLA policies scale with embodiment-free manipulation data. It combines over 100,000 hours of Universal Manipulation Interface (UMI) trajectories with post-training that aligns the policy to robots and human instructions.
Read it for
This is a useful reference for UMI data collection, VLA scaling laws, and data-efficient adaptation to new robot tasks. It separates broad action pretraining from the embodiment and instruction alignment needed for physical deployment.
Evidence boundary: The out-of-the-box experiments use task types seen in post-training; unseen environments and objects do not mean unseen tasks. New-task results require additional demonstrations, and RoboSkin has not reproduced the reported experiments.
Method, evaluation and access
- Method
- A vision-language model automatically labels trajectory clips with descriptions of scene state transitions. Cross-embodiment post-training then teaches the policy to act on particular robots and follow imperative task instructions.
- Evaluation context
- The study includes four simulation benchmarks, four familiar task types in unseen environments, and adaptation to four new physical-robot tasks. For new-task adaptation, the authors report 75% average success from 10 trials per task after fine-tuning on 36 hours of demonstrations in total.
- Artifacts and access
- The official repository records a 3 August 2026 release of post-training, inference, and evaluation code. Apache-2.0 code and a public 5B checkpoint are available, superseding the paper's earlier 'will be released' wording.
CVPR 2026 paper; first preprint November 2025
First published
Evo-1
Evo-1: Lightweight Vision-Language-Action Model with Preserved Semantic Alignment
Evo-1 is a 0.77-billion-parameter VLA model designed to preserve a pretrained vision-language model's semantic representations while learning robot control. It explores a compact alternative to policies that depend on large-scale robot-data pretraining.
Read it for
Use it to study lightweight VLA models, two-stage action alignment, and the practical constraints of robot-policy inference. The official repository also provides evaluation and deployment instructions for several robot platforms.
Evidence boundary: 'Without robot-data pretraining' still involves a pretrained vision-language backbone and task-specific robot demonstrations. The physical evaluation covers four tabletop tasks, and RoboSkin has not reproduced the results or hardware-dependent inference measurements.
Method, evaluation and access
- Method
- Evo-1 combines a native multimodal backbone, a cross-modulated diffusion transformer, and an integration module for visual, language, and robot-state features. Two-stage training progressively aligns action generation with the pretrained representations.
- Evaluation context
- The paper evaluates Meta-World, LIBERO, and RoboTwin simulation suites, plus four xArm6 manipulation tasks. Its reported 78% average physical-task success follows 100 training demonstrations and 20 evaluation trials per task.
- Artifacts and access
- The CVPR 2026 proceedings confirm the conference publication. The official MIT-licensed repository provides code, evaluation instructions, and model-weight links, with documented updates through August 2026.
Short answer
What you need to know
- 1
A robot vision-language-action model, usually shortened to VLA, uses visual observations and language instructions to produce or condition robot actions. Implementations differ in action representation, training data, embodiment coverage, control rate, and whether a separate planner or controller is required.
- 2
A VLA is not automatically a world model or an embodied reasoning system. A world model predicts future state; embodied reasoning can decompose and monitor tasks; a VLA maps observations and instructions toward physical action.
- 3
Touch can extend a VLA during contact-rich manipulation by adding pressure, shear, slip, deformation, or contact-state evidence. The useful test is whether tactile input changes closed-loop outcomes under matched conditions.
Topic 01
How to choose a VLA model for your robot
There is no single best VLA model across robots and tasks. Use the source-reviewed model index below to reject incompatible candidates before comparing success rates. The following decision order does not change the individual records or their review dates.
| Your requirement | First check | Next step |
|---|---|---|
| Run an available policy | Code, checkpoints, inference recipe, hardware requirements and separate licenses. | Distinguish a project-page announcement from runnable artifacts; reproduce the documented example first. |
| Adapt to your robot | State fields, action units, coordinate frame, gripper convention and normalization. | Compare with your dataset and controller contract before fine-tuning. |
| Use live tactile feedback | A documented tactile input and a trained pathway that can influence the action. | Use the tactile mechanism map; adding a dataset column does not establish model support. |
| Recover during contact | Control timing, intervention rules, disturbances and measured recovery on a matching task. | Evaluate a matched vision-only or no-touch baseline and report failures with trial counts. |
Topic 02
What enters and leaves a robot VLA
The common high-level description is vision plus language to action, but real systems also use robot state, action history, camera geometry, embodiment identifiers, depth, force, tactile signals, or a high-level plan. The output may be joint commands, end-effector motion, action chunks, discrete tokens, trajectories, or inputs to another controller.
Because the interface differs, model names and parameter counts do not create a fair performance ranking. Readers need the task, robot, data, action space, inference setting, and evaluation protocol.
Topic 03
How do vision-language-action models work? An architecture walkthrough
A useful vision-language-action model architecture has three interfaces to inspect: observations entering the model, multimodal features carrying task context, and an action head producing commands. A camera image and an instruction such as "place the cup on the tray" are encoded together; robot state may supply the current pose or gripper position. The action head then predicts values in the action representation used during training.
Architectures differ in how they generate those values. An autoregressive head can decode discrete action tokens in sequence. Diffusion or flow-matching heads can generate continuous action sequences through iterative refinement. These are design choices, not an automatic quality ranking: the robot interface, training coverage and inference budget still determine whether a model is a candidate for a task.
| Architecture interface | What to inspect | Failure to catch before deployment |
|---|---|---|
| Observation encoder | Camera views, image size, language prompt, robot state and history. | Missing views or a different state order can change the input seen by the trained policy. |
| Multimodal backbone | How visual, language and robot features interact; which parts are adapted. | Language understanding alone does not establish a learned robot action mapping. |
| Action head | Tokens or continuous values, action dimensions, horizon and decoding steps. | A valid output tensor may still use the wrong frame, units or gripper convention. |
| Execution adapter | Unnormalization, command limits, timing and controller interface. | The commanded action and the action physically executed can differ. |
Topic 04
Action chunks, continuous trajectories and feedback timing
An action chunk is a sequence of future commands predicted together. Predicting a longer chunk can reduce how often the model must run, but executing the entire sequence before observing again also delays reaction to a changed scene or unexpected contact. Prediction horizon, executed horizon and controller frequency are separate settings: a model can predict many steps while the robot executes only a prefix and then replans.
The October 2026 Vela preprint explores a different output representation: a fixed set of spline control points plus a motion-dependent horizon describes a continuous trajectory. The trajectory can be sampled at chosen control times. This is a useful example of current research on action representation; sampling more often does not mean the model receives new observations or makes a fresh decision at every sample.
For tactile manipulation, trace the complete feedback route. If slip is detected during a chunk, determine whether it can trigger a new policy call, change a residual controller, interrupt execution or only enter the next scheduled observation. A faster command stream alone does not prove faster contact response.
Topic 05
VLA, VLM, world model and embodied reasoning
These model categories can be connected inside one system, but they answer different questions. Keeping the roles separate makes research comparisons more useful.
| Model role | Core question | Typical output | Touch opportunity |
|---|---|---|---|
| Vision-language model | What is in the scene and what does the instruction mean? | Text, labels, plans, spatial or semantic representations | Describe contact context or interpret tactile-language pairs |
| Vision-language-action model | What should the robot do next? | Robot action, action token, trajectory, or action chunk | Use live touch to refine contact-rich actions |
| World or world-action model | What state may follow this action? | Predicted visual, tactile, latent, reward, or contact future | Predict slip, force-related state, or future tactile observations |
| Embodied reasoning system | How should a long task be decomposed, monitored, and recovered? | Subgoals, tool calls, constraints, or task status | Use contact as evidence that a physical step succeeded or failed |
Topic 06
Data and embodiment determine the model boundary
Robot data is heterogeneous: cameras, calibration, joint layouts, control spaces, grippers, hands, task labels, demonstration quality, and reset policies differ across platforms. A multi-embodiment model must represent those differences rather than assume that all actions share the same meaning.
Dataset size alone does not establish coverage. Evaluate which robots, tasks, environments, failure cases, sensor streams, and licenses are present, and whether test splits prevent leakage from repeated trajectories or objects.
Topic 07
Where tactile sensing fits
Most VLA descriptions start with images and instructions. Contact-rich tasks create a second timescale: visual planning may operate relatively slowly while slip, force, or local deformation can require faster feedback. A tactile pathway can enter the main policy, a specialized contact controller, a predicted future, or a high-frequency correction layer.
The reviewed tactile systems now expose six materially different integration paths. T-Rex adds multi-rate tactile refinement; ReTouch recursively refreshes predicted touch and the remaining action suffix; τ uses future visual change to supervise tactile representations during training; UniTacVLA combines semantic touch reasoning, future-touch prediction, and residual correction; ViTaR restricts touch to bounded residual modulation around a frozen VLA; and VLA-Touch separates tactile-assisted planning from action interpolation.
Their source-reported results belong to different robots, datasets, trial units, scoring rules, baselines, and artifact states. The mechanism map below preserves those boundaries and deliberately publishes no cross-paper rank score.
Topic 08
How to evaluate a robot VLA
A robust evaluation should identify the training resources, robot embodiment, task family, visual conditions, action interface, control rate, inference hardware, intervention rules, and real-robot trial protocol. Generalization should name what changed: object, scene, instruction, robot, sensor, task, or dynamics.
- Compare against matched policy and no-language or no-touch ablations where the claim requires them
- Report task completion, speed, recovery, safety constraints, and physical side effects rather than only offline loss
- Separate simulation, replay, benchmark, staged demonstration, and repeated real-robot evidence
- Check whether the model, code, weights, data, and evaluation procedure are actually accessible
Topic 09
Model ecosystem and release boundaries
The detailed index separates eleven VLA records. Gemini Robotics 2, RT-2, OpenVLA 7B, π0, and Isaac GR00T N1 do not document live tactile input in the reviewed releases. T-Rex, ViTaR, ReTouch, τ, UniTacVLA, and VLA-Touch do. In the August 22 source review, T-Rex exposed a comparatively complete combination of public checkpoints, model code, inference code, and a downloadable tactile dataset subset.
The August 22 review recorded ReTouch as paper-only, with ViTaR and τ announcing code to come. A September 15 check of the linked repositories still found UniTacVLA to be a project-page placeholder and VLA-Touch to provide partial code and resource links while marking its modified RDT inference implementation for future release. A paper, repository shell, dataset, controller checkpoint, and complete reproducible policy are different resources; project links alone do not establish successful reproduction.
Use this comparison for action interfaces and tactile feedback. For broader pretraining and transfer questions, continue to the robot foundation-model directory. Dataset, benchmark, and manipulation guides provide the task and evaluation context needed to judge a model for your own robot.
Topic 10
Open-source and efficient vision-language-action models: deployment choices
When looking for open-source vision-language-action models, check code, weights, training data and licenses separately. A public repository or downloadable checkpoint does not establish an unrestricted license or a complete reproduction. The model records below preserve release-specific evidence; the checklist here helps turn an available release into a deployment shortlist.
Efficient vision-language-action models should be compared using an end-to-end budget. Measure observation capture and preprocessing, model inference, communication, action decoding and execution delay on the intended hardware. Parameter count, tokens per second or an author-reported inference rate alone does not tell you how old the observation is when the robot moves.
| Deployment choice | Practical benefit to investigate | Tradeoff to measure |
|---|---|---|
| Smaller backbone or fewer input tokens | Lower memory use or shorter inference time. | Task success under occlusion, small objects and varied instructions. |
| Fewer action-generation steps or compressed action output | Less decoding work per prediction. | Action precision, smoothness and recovery under the same task protocol. |
| Longer chunks or asynchronous inference | More continuous command delivery between model calls. | Observation age, interruption behavior and reaction to unexpected contact. |
| Local versus remote inference | Fit available compute and integration constraints. | Communication delay and variability, data handling, and behavior if a response is late. |
Topic 11
Before using vision language action models, check the data contract
Vision language action models connect visual observations and instructions to action outputs, but their runnable recipes accept specific data interfaces. The two public recipes below illustrate why a dataset directory or shared container format is not enough. These README-level requirements were checked on September 16, 2026; training and inference were not run for this review.
The model index below retains its model-specific source-review dates, input modalities, artifact availability, training-data summaries and original sources. The broader robot foundation-model page covers the wider model taxonomy; this page focuses on action interfaces and the evidence for live tactile input. Unconfirmed means the reviewed source does not establish a capability, not that the capability is impossible.
| Recipe and primary source | Input / code | Data requirement | Tactile support in this recipe |
|---|---|---|---|
| OpenVLA base recipe [S1] | README inference example uses an image and language prompt; public repository contains fine-tuning code. | Documented training loader uses RLDS mixtures; custom data needs conversion/registration and matching observation/action transforms. A LeRobot folder is not a direct replacement. | Unconfirmed in the reviewed base README. Do not infer support from the ability to store an additional column. |
| OpenPI π0 / π0.5 recipes [S2] | Public code and checkpoints; image, prompt and robot state processing depend on the selected policy configuration. | The custom-data guide uses LeRobot conversion, a data configuration, input/output transforms and state/action normalization. Match the pinned dependency and selected embodiment; this does not establish support for every v3 export. | Unconfirmed in these reviewed recipes. A tactile-aware adapter and trained pathway would require separate evidence. |
Source-reviewed evidence index
VLA interfaces, embodiments, access and touch
Compare each model's inputs, actions, tested robots, code and weight access, and tactile feedback. Results belong to the robots and tasks in each source; they are not a shared benchmark. Follow the source links to check a release or open the full evidence record for more context.
- 11
- verified VLA records
- 6
- with verified tactile input
- Primary
- source requirement
| Model / release | Inputs / action output | Verified embodiments | Real-robot evidence | Training / access / touch | Evidence boundary / sources |
|---|---|---|---|---|---|
| Gemini Robotics 2Google DeepMindFull evidence record | Inputs: Text instruction; RGB image Output: Motor-control actions |
| Google DeepMind reports developer-run whole-body, multi-finger, and parallel-gripper task trials on Apollo 2 and Franka Duo configurations. | Training / data: The reviewed official model page and release post do not disclose the training-mixture composition, example count, or complete data provenance. Access: Private preview; organizations can join the official early-access waitlist. License: Model weights and a reusable model license are not publicly disclosed; access is governed by private-preview terms. Tactile input: Not documented | The public model specification lists text and image inputs, not touch. Results are developer-reported on selected hardware and tasks; no public weights, training recipe, neutral cross-platform benchmark, or model-specific research paper was verified.Reviewed 2026-08-21 |
| RT-2Google DeepMindFull evidence record | Inputs: Robot-camera image; Natural-language instruction Output: Tokenized robot actions |
| The paper reports 6,000 evaluation trials covering seen and unseen task conditions on the authors’ real-robot setup, alongside Language Table simulation tests. | Training / data: PaLM-E- and PaLI-X-based variants were co-fine-tuned on web-scale vision-language data and RT-1 robot demonstrations gathered with 13 robots over 17 months. Access: Paper and official technical description are public; model weights and a runnable training implementation were not released. License: No public model-weight license was disclosed because weights were not released. Tactile input: Not documented | RT-2 is a closed research model evaluated mainly within the authors’ mobile-manipulation environment. Its image-and-language interface does not document tactile input, and reported generalization should not be transferred to untested robots, sensors, tasks, or safety conditions.Reviewed 2026-08-21 |
| OpenVLA 7BStanford University, UC Berkeley, Toyota Research Institute, Google DeepMind, Physical Intelligence, and MITFull evidence record | Inputs: Natural-language instruction; RGB robot observation Output: Discretized robot actions |
| The paper reports real-world evaluation across 29 manipulation tasks and multiple robot embodiments, comparing task success with generalist-policy baselines. | Training / data: The flagship 7B model was trained on 970,000 real-world robot trajectories from the Open X-Embodiment mixture. Its published mixture includes DROID at 10% before DROID is removed for the final third of training, plus a 13.3% Bridge bucket that combines Bridge V1 and BridgeData V2 rather than reporting a V2-only share. Access: Training and inference code plus pretrained checkpoints are public through the official project and repository. License: Repository code is MIT; the maintainers state that pretrained models can inherit restrictions from their underlying base models, so each checkpoint’s terms must be checked. Tactile input: Not documented | The released flagship model is vision-language-action rather than tactile. Reported task success is tied to the paper’s action representation, data mixture, platforms, and protocol; “open source” does not remove inherited base-model license restrictions.Reviewed 2026-08-22 |
| π0 (Pi Zero)Physical IntelligenceFull evidence record | Inputs: RGB images; Natural-language instruction; Low-dimensional robot state Output: Continuous robot-action chunks generated by flow matching |
| The original release evaluates five complex real-world task families, including laundry folding, table bussing, grocery bagging, box assembly, and object retrieval. | Training / data: The original report combines a pretrained vision-language backbone with 903 million steps of proprietary robot data plus a 9.1% open-source mixture containing an Open X-Embodiment subset, BridgeData V2, and DROID; it does not disclose separate weights for those three sources. Current OpenPI base checkpoints report pretraining on more than 10,000 hours of robot data. Access: OpenPI publishes Apache-2.0 code, base checkpoints, and selected task-specific checkpoints; the maintainers warn that adaptation to a new platform may fail. License: Apache-2.0 for the OpenPI repository; users must also follow the licenses attached to checkpoints, base-model components, and training datasets. Tactile input: Not documented | The published input schema uses images, language, and robot state rather than touch. Original comparisons use the authors’ scoring rubric and platforms; current open checkpoints and code have evolved since the 2024 report and do not guarantee reproduction on other hardware.Reviewed 2026-08-22 |
| Isaac GR00T N1NVIDIAFull evidence record | Inputs: Natural-language instruction; RGB image; Robot state Output: Robot actions from a vision-language module and diffusion-transformer action module |
| The N1 research page reports language-conditioned bimanual household manipulation on Fourier GR-1 and 1X humanoids, plus simulation benchmarks across embodiments. | Training / data: NVIDIA reports a mixture of egocentric human video, real robot trajectories, simulated robot trajectories, and synthetic data; complete example counts and item-level provenance are not disclosed in the research page. Access: The Isaac-GR00T repository publishes code and model checkpoints; the maintained family has advanced beyond the paper’s N1 release. License: Repository code is Apache-2.0 and model weights use the NVIDIA Open Model License; exact terms must be checked for the selected version. Tactile input: Not documented | The N1 report does not document tactile input. Real-robot evidence is developer-reported on named humanoids and household tasks; current repository defaults may implement later N1-family versions, so version-matched checkpoints and evaluations are required.Reviewed 2026-08-21 |
| T-RexUC Berkeley, NVIDIA, Stanford University, Panasonic, Sapienza University of Rome, and ItalAIFull evidence record | Inputs: Natural-language instruction; Head and bilateral wrist RGB video; Robot state; Ten fingertip tactile deformation streams and 6D wrench estimates Output: Bimanual robot-action chunks with approximately 5 Hz slow action generation and 20 Hz tactile refinement |
| The official project reports a 65% macro-average for T-Rex versus 35% for EgoScale across 12 contact-rich tasks, with 16 randomized rollouts per task on one fixed-base bimanual setup. | Training / data: The authors report three stages: large-scale tactile-free egocentric pretraining, tactile-reactive midtraining on the full 100-hour T-Rex collection, and task-specific post-training. The current public dataset card specifies 5,464 episodes and 5,473,459 frames at 30 FPS, approximately 50 hours, rather than the complete 100-hour training corpus. Access: Paper, project page, MIT-licensed repository, pretrained and midtrained checkpoints, post-training and inference code, full-pipeline branch, and an approximately 50-hour LeRobot v3.0 dataset subset are public. License: The official repository, Hugging Face midtraining checkpoint, and public dataset card are marked MIT; upstream models, dependencies, hardware assets, and any unbundled corpora retain their own terms. Tactile input: Documented | T-Rex is a June 2026 arXiv preprint with developer-run results on one Dexmate Vega-1 and dual Sharpa Wave configuration. The 65% score uses source-defined progress rubrics, and the released approximately 50-hour subset is not the complete 100-hour corpus used for tactile-reactive midtraining; no independent reproduction or cross-platform evaluation was verified. T-Rex preprint ↗T-Rex official project ↗T-Rex official repository ↗T-Rex midtraining checkpoint card ↗ Reviewed 2026-08-22 |
| ViTaRBeijing Institute of TechnologyFull evidence record | Inputs: Natural-language instruction; Primary scene or head RGB image; Wrist RGB image; Robot proprioception; Marker-derived contact descriptor; Bilateral tactile-image summary Output: Frozen OpenVLA-OFT action chunk plus an optional bounded 7D end-effector residual selected and scaled from current contact evidence |
| The authors report binary end-to-end success on three physical tasks with 20 trials per method-task pair: 40% on Insert Hole, 65% on Lift Bottle, and 40% on Wiping the Board, or 48.3% across those tasks. A separate seven-task UniVTAC protocol uses 100 episodes per method-task pair and reports a 61.3% average. | Training / data: The frozen OpenVLA-OFT reference is fine-tuned on 50 UniVTAC trajectories per task across seven tasks. ViTaR additionally uses 20 restored decision groups per task and short local branches to supervise effect ranking and residual modulation; trajectory, decision-group, branch, and preference-pair counts are different units and are not combined here as one demonstration total. Access: Paper, official project page, video, figures, and project-page source are public. The official page marks code as “Coming soon”; no runnable ViTaR implementation, model weights, EGM or RAM checkpoints, exact branch corpus, or ViTaR-specific dataset download was verified. License: No separate software, model-weight, checkpoint, or ViTaR-specific dataset license was published because those artifacts were not released. The upstream UniVTAC terms do not license ViTaR artifacts. Tactile input: Documented | ViTaR is an August 2026 v1 preprint with author-reported evidence. Its 61.3% UniVTAC binary-success average and 48.3% physical average use different cohorts and must not be combined or ranked against unlike VLA protocols. Imported, adapted, and author-evaluated baselines do not share identical upstream data, seeds, or interaction budgets, and ViTaR receives additional branch supervision. Physical evidence is limited to one RM65-B configuration, three tasks, and 20 trials per task; no independent reproduction, cross-robot transfer, or public implementation was verified.Reviewed 2026-08-22 |
| ReTouchUniversity of Science and Technology of China, iFLYTEK, and The Chinese University of Hong KongFull evidence record | Inputs: Natural-language task instruction; One wrist-mounted RGB view; Two fixed external RGB views; 18-dimensional robot proprioception; Current frame plus the preceding nine frames from five fingers with 120 three-axis force taxels per finger (a ten-frame input window) Output: Sixteen-step chunks of 18-dimensional absolute joint-position commands, with the remaining suffix regenerated from updated tactile observations during execution |
| The standard protocol uses 20 real-robot rollouts per method on each of seven tasks and reports an 83.6% macro-average normalized task score. Button Press is binary, while the other six tasks award weighted partial credit. Four separate challenging settings also use 20 rollouts per method-setting and report a 73.1% macro-average for ReTouch. | Training / data: XHT-Dataset contains 900 retained successful demonstrations across seven real-world tasks. The paper holds out 100 trajectories from tactile-encoder and policy training and uses the remaining 800 as a common training pool; it does not disclose the per-task distribution or publish the split manifest or dataset files. Access: The current arXiv v2 paper is public. No paper-linked official project page, source-code repository, model weights, checkpoints, XHT-Dataset download, or exact split manifest was verified on 2026-08-22. License: No separate ReTouch software, model-weight, checkpoint, or XHT-Dataset license was verified because those artifacts were not publicly released. Tactile input: Documented | ReTouch is an August 2026 preprint evaluated by its authors on one XHand–UR7e setup. The paper calls the primary quantity “Success Rate,” but Appendix B defines it as a normalized task score and only one of seven tasks is binary; 83.6% therefore must not be described as 83.6% fully completed trials. One on-site evaluator applies the rubric, each task or challenge has 20 rollouts per method, and no confidence intervals, public logs, independent replication, artifact release, or cross-platform evaluation was verified.Reviewed 2026-08-22 |
| τ (Touch-Augmented VLA)Beijing Jiaotong University and Beijing Institute for General Artificial IntelligenceFull evidence record | Inputs: Natural-language instruction; Multi-view RGB observation; Robot proprioception; Bilateral vision-based tactile deformation Output: Future robot-action chunks generated by a π0.5-based conditional flow-matching policy; exact action dimension and semantics are not reported |
| Each fixed model variant is evaluated for 20 trials per task across four physical tasks. The best fixed variant by the paper’s reported mean is τ-Wrist at 71.25%, with full-task success of 60%, 40%, 90%, and 95%; a separate sentence mixes best task values from different variants and is not treated as one checkpoint result. | Training / data: TacAura supplies 100 human-teleoperated demonstrations per task across plug insertion, USB insertion, stamp pressing, and whiteboard erasing. A JEPA-style auxiliary branch uses current touch and subsequent actions to predict future visual-feature changes during training; that predictive branch is removed at inference, while tactile input remains part of the deployed policy. Access: The arXiv v3 paper and project page are public. The project labels code “Coming Soon,” but its button points to a separate STOLA placeholder; no τ implementation, model weights, TacAura download, data-conversion tools, or reusable artifact license was verified. License: No software, model-weight, or TacAura dataset license was verified because the promised artifacts were not released. Tactile input: Documented | τ is a July 2026 preprint with author-run results on one Franka Research 3 and bilateral DM-Tac WS configuration. Baselines marked with a dagger were adapted to the authors’ tactile setup; results do not establish cross-embodiment or cross-sensor transfer. The paper does not report exact action semantics or deployment rate, omits tactile-aware world-model comparisons for computational reasons, and had not released code, weights, or TacAura by 2026-08-22. “No deployment overhead” applies only to removing the training-only predictive branch, not to the tactile sensing and encoding path used at inference.Reviewed 2026-08-22 |
| UniTacVLAHarbin Institute of Technology, Great Bay University, Shanghai Jiao Tong University, Fudan University, Nanjing University, and Daimon RoboticsFull evidence record | Inputs: Natural-language instruction; Wrist and first-person RGB observations; Robot state; Bilateral depth and shear tactile deformation; Predicted future tactile latents Output: Low-frequency π0.5 action chunks plus bounded high-frequency residual corrections conditioned on current and predicted tactile latents; exact action dimensions and rates are not reported |
| Eight subtasks are evaluated in clean and perturbed settings with 50 trials per subtask-setting. The paper publishes all 16 task-setting success rates but not an aggregate number, so RoboSkin preserves the per-task protocol rather than presenting a calculated mean as a paper-reported score. | Training / data: The paper reports approximately one hour of 30 Hz demonstrations per subtask across eight subtasks, with 80% normal expert demonstrations and 20% disturbance-recovery demonstrations. It does not disclose trajectory or frame counts, a named public dataset, an exact split manifest, or a downloadable corpus. Access: The arXiv v1 paper is public, while the official repository contains only a “coming soon” project-page placeholder. No implementation, checkpoint, training dataset, release, tag, or reuse license was verified. License: No public software, model-weight, or dataset license was verified because the repository remains a project-page placeholder without released artifacts. Tactile input: Documented | UniTacVLA is a June 2026 v1 preprint evaluated by its authors on one RM75B, one custom gripper, and two DM-Tac W sensors. The table reports 50 trials for each clean or perturbed subtask setting but no aggregate mean; calculated averages must not be presented as author-reported. Exact action dimensions, backbone and controller rates, trajectory count, tactile pixel resolution, severe-occlusion performance, explicit force or torque modeling, code, checkpoints, public data, and independent reproduction remain unavailable.Reviewed 2026-08-22 |
| VLA-TouchNational University of SingaporeFull evidence record | Inputs: Natural-language task goal; Overhead and wrist RGB observations; Robot proprioception; GelSight Mini tactile images; Octopi tactile-language descriptions; Marker-tracked low-dimensional tactile state Output: High-level primitive instruction plus an RDT-1B 64-step action chunk refined by a tactile and vision-conditioned interpolant controller |
| The complete planning-and-manipulation system is evaluated for 20 trials on each of three tasks and reports 9/20 complete Cup trials, 12/20 complete Wipe trials, and 7/20 complete Peel trials. Separate component tables also use 20 trials per condition and must not be merged with these end-to-end counts. | Training / data: The base RDT-1B policy is first aligned to the Franka action space and then fine-tuned per task without tactile input. The interpolant controller is trained on paired VLA-generated and expert action sequences from 380 demonstrations across the Cup, Wipe, and Peel task pipelines; the exact RDT task-checkpoint release is not verified. Access: The official MIT-licensed repository publishes partial controller and Octopi code and links a public processed dataset plus controller checkpoints. The modified RDT inference implementation is still marked for future release, no complete task-fine-tuned RDT checkpoint was verified, and the repository has no GitHub release. License: MIT applies to files in the official GitHub repository. No separate license was verified for the linked dataset, Drive-hosted controller checkpoints, Octopi data, or upstream RDT-1B artifacts. Tactile input: Documented | VLA-Touch is a modular wrapper rather than a released tactile-native foundation model. Evidence is limited to one single-arm Franka setup, one unilateral GelSight Mini, three tasks, and 20 trials per task. The authors test source-defined environmental variations rather than cross-task, cross-robot, or cross-sensor generalization. Octopi, GPT-4o, RDT-1B, BRIDGeR-derived control, data, and checkpoints have separate boundaries; the repository MIT license must not be generalized to those external or hosted artifacts, and the complete modified RDT deployment path remains unreleased.Reviewed 2026-08-22 |
Tactile VLA mechanism map
Six ways touch enters the action loop
These systems do not implement one interchangeable “tactile VLA” design. This evidence layer separates direct fusion, predictive supervision, future-touch refinement, slow-fast correction, bounded modulation, and dual-level planning. Reported scores remain inside each source protocol and are never normalized into a leaderboard.
6
mechanism records
0
cross-paper rank scores
2026-08-22
source review date
| System / integration role | Where touch enters | Action and control path | Evaluation / metric unit | Artifact boundary | Evidence boundary / sources |
|---|---|---|---|---|---|
| ViTaRbounded residual modulationFull model evidence | A marker-derived contact descriptor helps choose whether to retain the frozen VLA action or select a structured residual; a bilateral tactile summary scales the chosen residual with a gain in [0, 1]. | Frozen OpenVLA-OFT chunk → retain or select one bounded 7D residual direction → apply the same scaled residual across the chunk. Touch cannot invent a new base direction or alter the candidate set. | Evaluation unit: Seven UniVTAC tasks use 100 episodes per method-task pair; three physical RM65-B tasks use 20 trials per method-task pair. Metric: End-to-end binary task success. The reported 61.3% UniVTAC and 48.3% physical averages come from different cohorts and are not combined. | Paper and project page public; official page says code is coming soon. No runnable model, weights, EGM or RAM checkpoints, or exact branch corpus verified. | Author-reported v1 preprint evidence. Imported, adapted, and newly evaluated baselines do not establish equal upstream data, seed, or interaction budgets; physical evidence is limited to one configuration and three tasks.Reviewed 2026-08-22 |
| ReTouchonline tactile prediction refinementFull model evidence | A finger- and patch-aware encoder processes the current tactile frame plus the preceding nine frames, forming a ten-frame input window of dense five-finger force taxels. The deployed Foresight Action Expert recursively refreshes predicted tactile latents as new touch arrives. | Cached 9 Hz visual-language context → 36 Hz model-only Foresight Action Expert passes → regenerate the unexecuted suffix of a 16-step absolute joint-position chunk at offsets 4, 8, and 12. | Evaluation unit: Seven standard tasks and four separate challenge settings use 20 real-robot rollouts per method-task or method-setting on one XHand–UR7e platform. Metric: A normalized task score. Only Button Press is binary; the other six standard tasks award weighted partial credit, so the reported 83.6% macro-average is not a full-completion rate. | Paper only. No official implementation, checkpoint, XHT-Dataset download, split manifest, evaluation log, or artifact license verified. | Author-reported results with one on-site evaluator and no confidence intervals or independent replication. The 9 Hz and 36 Hz values are RTX 5090 model-only rates that exclude communication and controller scheduling.Reviewed 2026-08-22 |
| τ (Touch-Augmented VLA)future-visual supervised tactile fusionFull model evidence | Bilateral vision-based tactile deformation is encoded and fused into a pretrained π0.5 policy. During training, current touch and subsequent actions predict future visual-feature change; that auxiliary JEPA-style branch is removed at inference. | Multi-view RGB + language + proprioception + live bilateral touch → fused VLA representation → flow-matched future action chunk. Live touch remains an inference input even though the predictive supervision branch is removed. | Evaluation unit: Four physical tasks use 20 trials per fixed model-task pair on one Franka Research 3 and bilateral DM-Tac WS configuration. Metric: Stage and full-task success. The best fixed variant by reported mean is τ-Wrist at 71.25%; a textual list mixing best task values from different variants is not treated as one checkpoint result. | Paper and project page public; code is labeled coming soon and links to a separate placeholder. No τ implementation, weights, TacAura download, or reuse license verified. | Author-run preprint evidence with tactile baselines adapted to the local sensor setup. No cross-robot or cross-sensor transfer is tested, and “no deployment overhead” applies only to the removed auxiliary branch.Reviewed 2026-08-22 |
| UniTacVLApredictive tactile residual controlFull model evidence | Unified tactile tokens receive semantic contact-state supervision and coarse-to-fine future tactile prediction. Current and predicted tactile latents both condition a separate action-tactile mixed controller. | π0.5 low-frequency action chunk → predicted tactile prior + current touch + robot-state update → bounded high-frequency residual correction. The paper does not disclose either rate or the action dimension. | Evaluation unit: Eight physical subtasks are each tested in clean and perturbed settings with 50 trials per subtask-setting on one RM75B configuration. Metric: Per-subtask binary success rates. The paper table does not print an aggregate mean, so RoboSkin does not label a calculated overall average as author-reported. | Paper public; official repository is a one-line coming-soon project placeholder with no code, checkpoints, dataset, release, tag, or license. | Author-reported v1 evidence on one custom gripper and sensor pair. Exact trajectory count, tactile resolution, action interface, control rates, severe-occlusion evidence, public data, and independent reproduction are unavailable.Reviewed 2026-08-22 |
| T-Rexmulti-rate tactile action refinementFull model evidence | Ten fingertip deformation streams and derived wrench estimates provide a fast tactile-reactive path alongside head and wrist video, language, and robot state. | Approximately 5 Hz slow VLA action generation → approximately 20 Hz tactile refinement → bimanual action chunks for a fixed Dexmate Vega-1 and dual Sharpa Wave configuration. | Evaluation unit: Twelve contact-rich tasks use 16 randomized rollouts per task on one fixed-base bimanual platform. Metric: Source-defined progress or success rubrics with a reported 65% macro-average. This protocol is not a shared leaderboard with the other tactile VLA records. | MIT repository, checkpoints, training and inference code, and an approximately 50-hour public LeRobot subset are available; the public subset is not the complete reported 100-hour corpus. | Developer-run preprint evidence on one platform. No independent reproduction or cross-platform evaluation is verified, and the released data boundary must remain separate from the full training-corpus claim.Reviewed 2026-08-22 |
| VLA-Touchdual-level planning and action refinementFull model evidence | At the planning level, Octopi and marker tracking turn GelSight observations into linguistic tactile evidence for GPT-4o. At the execution level, marker-tracked touch conditions an interpolant controller around a non-tactile RDT-1B policy. | Tactile-informed primitive instruction → RDT-1B 64-step source chunk → DINOv2, robot state, and tactile-conditioned interpolant refinement of the action chunk. | Evaluation unit: Cup, Wipe, and Peel each use 20 end-to-end trials on one Franka Panda, Robotiq 2F-140, and unilateral GelSight Mini setup. Metric: Binary end-to-end counts for the complete system: 9/20 Cup, 12/20 Wipe, and 7/20 Peel. Separate planning and manipulation component tables are not merged into those counts. | MIT repository with partial controller and Octopi code plus linked data and controller checkpoints. Dataset and hosted checkpoint licenses are not verified, and the modified RDT inference implementation remains unreleased. | A modular wrapper rather than a tactile-native foundation VLA. Evidence is task- and hardware-specific; it does not establish cross-task, cross-robot, or cross-sensor generalization or a complete reproducible deployment path.Reviewed 2026-08-22 |
Paper routes
Start with source-backed RoboSkin briefs
 Tactile manipulation / 2026-08-22T-Rex adds high-rate tactile reaction to dexterous robot policiesT-Rex reports a 100-hour collection and a 30-point gap over EgoScale; its official release now provides code, checkpoints, and an approximately 50-hour public subset.
 Tactile AI / 2026-08-15Dream-Tac: A Unified Tactile World Action Model for Contact-Rich Robot ManipulationDream-Tac models action-conditioned tactile futures for contact-rich robot manipulation, showing why robot skin data needs prediction, not only reaction.Tactile AI / 2026-08-15FeelWorld predicts contact, tactile force states, and slip for robot planningFeelWorld adds explicit contact, force-related tactile, and slip prediction to a visual world model for contact-rich robot planning.
Common questions
FAQ for this topic
What is a robot VLA model?
A robot vision-language-action model uses visual observations and language instructions to produce or condition robot actions. Architectures and action interfaces vary, so the term does not specify one model design.
Where can I find VLA model code and weights?
OpenVLA’s official project links its code and model checkpoints. Access differs across other VLA systems: some release weights and training code, while others provide a paper, a repository placeholder, or only selected controllers and datasets. Check the access and license fields for the exact release before planning a reproduction.
What is the difference between UniTacVLA and VLA-Touch?
UniTacVLA combines tactile understanding, future-touch prediction, and residual action correction. VLA-Touch adds tactile-language feedback to planning and uses a controller to refine VLA actions. Their robots, evaluation protocols, and public artifacts differ, so the reported results are not directly comparable.
Is a VLA the same as a robot foundation model?
Not always. A VLA may be trained as a broad reusable foundation model or for a narrower robot and task set. Foundation-model claims require evidence for transfer, adaptation, or reuse.
Do robot VLA models use touch?
Some do, but many are vision-language-action systems without live tactile input. Touch may be fused into the policy, used by a fast correction layer, or predicted by a world model.
How should VLA models be compared?
Compare them only after aligning robot embodiment, tasks, inputs, action space, data, baselines, control rate, and real-robot evaluation. Unlike settings should not be collapsed into a leaderboard.
How do vision-language-action models work?
They encode visual observations and a language instruction, often together with robot state, then generate actions through a trained action head. The output may be discrete tokens, continuous action chunks or trajectory parameters. An execution adapter and robot controller must interpret that output in the documented units, frame and timing.
What makes a vision-language-action model efficient for deployment?
Efficiency depends on memory, observation processing, inference, communication and action execution on the target hardware. Smaller models, compressed outputs and fewer decoding steps can reduce computation, but compare task success and feedback delay as well. A high controller frequency does not establish that the model replans at the same rate.
Which vision-language-action model benchmark should I use?
Choose a benchmark that matches the claimed task and generalization setting, then keep the embodiment, observation streams, action interface, training data and evaluation budget aligned. Simulation and real-robot trials answer different questions. For tactile claims, include a matched no-touch comparison and contact-related outcomes rather than relying only on a general manipulation score.